Tech giants don't accidentally vacuum up billions of dollars worth of copyrighted journalism. They know exactly what they are doing.
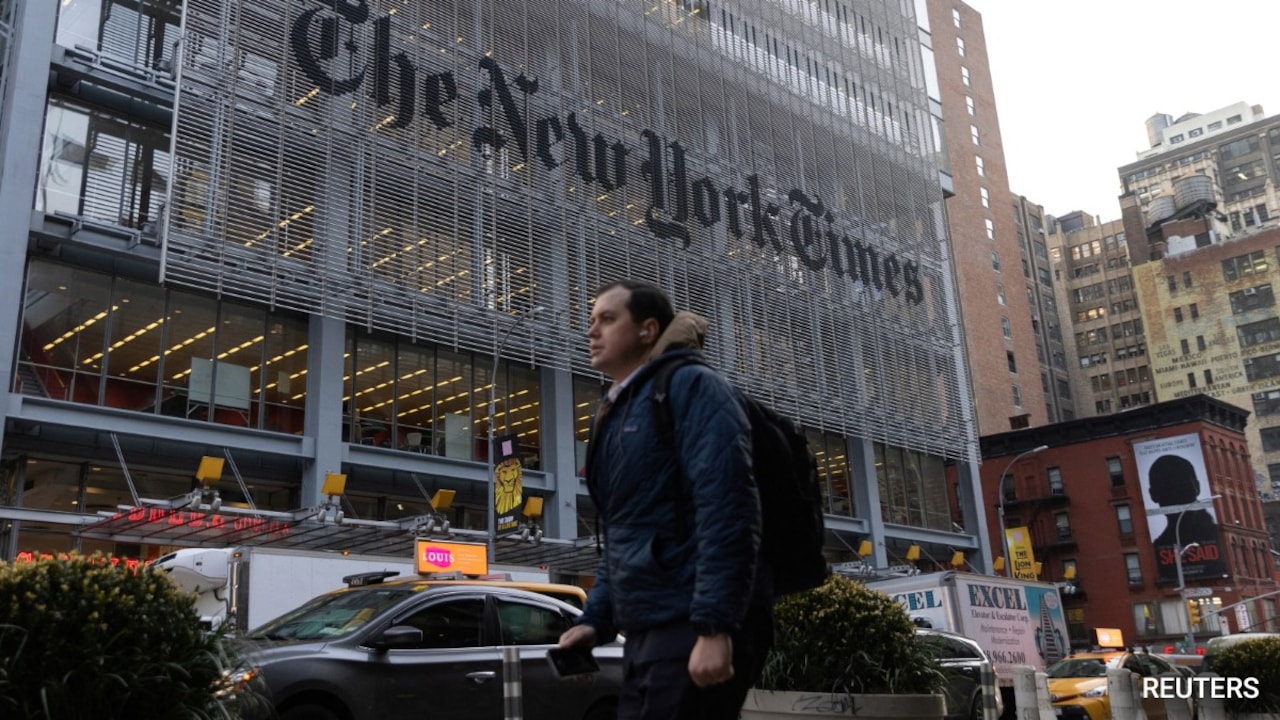
Recent unsealed court documents from the ongoing legal battle between The New York Times, Microsoft, and OpenAI reveal a smoking gun. Behind closed doors, internal communications showed tech executives recognizing that scraping copyrighted text without permission or compensation crossed a massive legal line. One Microsoft executive even privately labeled large language model web scraping an astonishing act of theft. Yet, the data harvesting continued at full throttle to feed hungry artificial intelligence models. Don't miss our recent coverage on this related article.
If you have been following the collision course between generative artificial intelligence and traditional publishing, this revelation shouldn't shock you. But it strips away the last remnants of plausible deniability for Silicon Valley.
The Anatomy of Digital Land Grabs
Silicon Valley operates on a simple mantra: move fast and break laws, deal with the lawsuits later. When companies like OpenAI build massive language models, they require unprecedented volumes of human-written text to sound articulate, coherent, and factual. High-end journalism provides the exact gold standard of linguistic quality they need. If you want more about the context of this, Mashable offers an in-depth breakdown.
Instead of negotiating fair licensing deals from day one, tech firms deployed aggressive web scrapers to ingest paywalled investigations, daily reporting, and deeply researched columns. They bypassed the subscription models that keep newsrooms alive.
When publishers pushed back, the standard defense was predictable. Tech representatives argued that training artificial intelligence on publicly accessible web pages falls under fair use. They framed it as the digital equivalent of a human reading a library book.
That argument collapses when internal emails expose executives privately worrying about copyright infringement and intellectual property theft. You don't panic about internal legal exposure if you genuinely believe your practices are entirely legal and above board.
Why This Legal Fight Changes Everything
The legal battle moving through the U.S. District Court for the Southern District of New York isn't just about one newspaper. It is an existential threat to how tech companies source training data.
The plaintiffs have pushed for a summary judgment. If a judge rules heavily in favor of the publishers, the financial fallout will ripple across the entire tech ecosystem. We are talking about billions in potential damages or forcing companies to purge models trained on contested data. Purging a foundational model means throwing away billions of dollars in compute power and starting over.
Some publishers have chosen to cut licensing deals, taking payouts ranging from modest annual sums to multi-million dollar partnerships. But signing a deal out of economic desperation is very different from a fair market exchange. Smaller independent outlets lack the legal war chests to fight back, leaving them vulnerable to having their lifelines harvested for free.
The Broader Fallout for Content Creators
This dispute extends far beyond elite newspapers. Every writer, creator, and independent publisher faces the same existential threat. When artificial intelligence can instantly summarize or regurgitate paywalled reporting without driving a single click back to the original source, the economic engine of the internet breaks down.
If investigative journalism stops being profitable, original reporting dies. And if original reporting dies, artificial intelligence models will soon find themselves feeding entirely on their own synthetic sludge, regurgitating recycled summaries of recycled content.
The documents exposed in the New York Times lawsuit prove that the architects of the artificial intelligence boom knew the risks and proceeded anyway. Accountability is finally catching up to them. The outcome of this case will decide whether original human labor still has value in an automated world.